A scheduled backup is running, but nobody checks failures. Is that a control?
Unowned operational assuranceA scheduled job needs monitoring, response ownership, and periodic verification of its result. Assign responsibility for failures and for checking that the protected scope remains correct as the service changes. Automation without an accountable response can fail silently.
What to do now
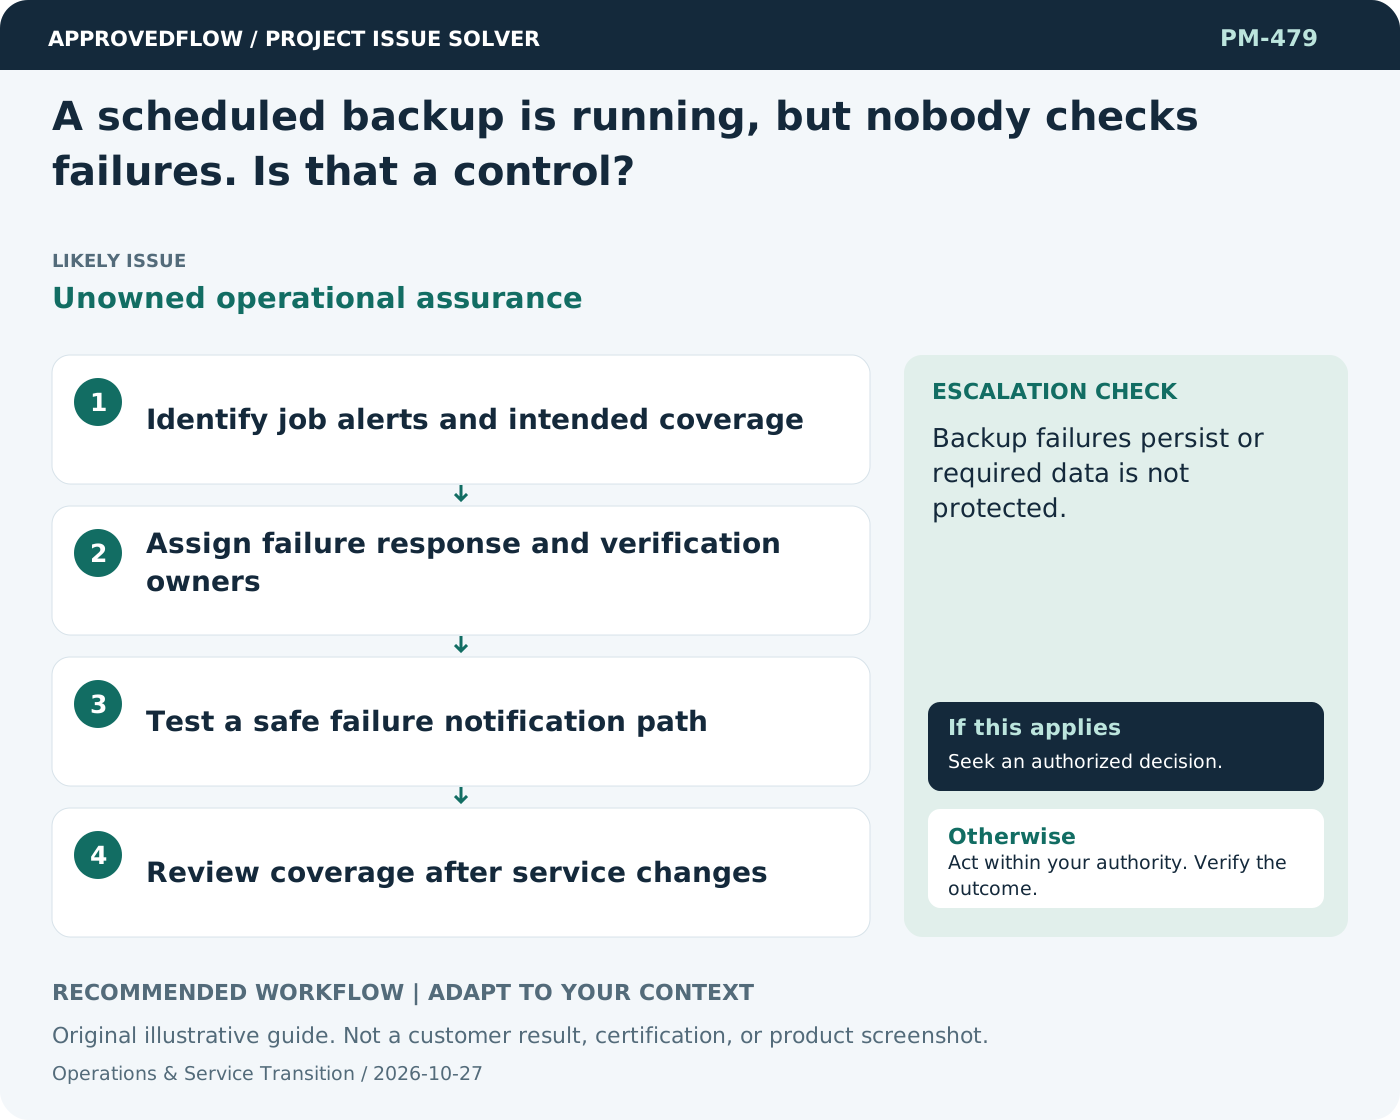
- Identify job alerts and intended coverage
- Assign failure response and verification owners
- Test a safe failure notification path
- Review coverage after service changes
When to escalate
Backup failures persist or required data is not protected.
The service owner and authorized operational decision maker
Example
A backup alert reaches an accountable operator who verifies recovery coverage after a new database is added.
Mistake to avoid
Assuming a scheduled automation is self-managing.
Prevent a repeat
Test whether receiving teams can operate and recover the service without depending on informal project-team support.
Suggested ApprovedFlow setup
- Tasks
- Documents
- Approvals
Keep handover tasks, operating evidence and the acceptance decision linked to the project while retaining monitoring and incident control in the actual service tools. See the platform
Related cases
- Business data errors continue after launch. Who should fix them?Undefined operational data ownership
- Monitoring shows servers are healthy, but users cannot complete transactions. Why?Infrastructure-only service monitoring
- How do we distinguish quality assurance from quality control?Process-versus-output checks
- Security review is scheduled one week before launch. What should I do?Late security assurance